4 min read
What is a large language model, and what are its limitations?
An introduction to tokens, training and response generation, and why fluent, confident answers still need evaluation.
ChatGPT, Claude, Gemini and most of the AI assistants people use every day are built on the same kind of system: a large language model, or LLM. Understanding the model’s operation helps clarify its capabilities and limitations. This is a plain explanation of what such a model actually does, how it becomes an assistant, and the limits that matter when you build something with one.
Text in pieces: tokens
A language model never sees letters or words directly. Before anything else, text is cut into tokens: short pieces that are often a whole common word, part of a longer word, a space with a word, or a punctuation mark. Each token has a number, and the model works only with those numbers.
The split is decided once, before training, by a tokenizer built from a large sample of text. Pieces that are frequent in that sample become single tokens; rare ones are spelled out in several. That has a practical consequence for languages that were a smaller part of the sample, Persian among them: the same sentence often takes more tokens in Persian than in English. Tokens are what models are priced and limited by, so it is worth measuring with your own text rather than assuming.
One job: predict the next token
Underneath everything, an LLM does one thing. Given a sequence of tokens, it gives a probability for every token that could come next. To write a reply, the software around it picks one of the likely tokens, adds it to the sequence, and asks again, one token at a time, until it reaches a stopping point.
How the next token is picked matters. Always taking the single most likely token gives safe but repetitive text; sampling among the likely ones, controlled by a setting usually called temperature, gives more varied text. Low temperature suits extraction and classification; higher suits drafting and brainstorming.
Where the knowledge comes from
The probabilities come from training. A model starts as a large network of numbers (its parameters or weights, today counted in billions) set at random. It is shown an enormous amount of text and, at each position, asked to predict the next token; every wrong guess nudges the weights a little towards the right one. Repeated over a vast amount of text, this teaches grammar, facts, styles of writing and some ability to follow an argument, all stored implicitly in the weights.
Almost every current LLM uses the Transformer architecture, introduced by researchers at Google in 2017 in the paper Attention Is All You Need. Its central idea, attention, lets each token weigh every earlier token in the sequence when the next one is predicted, which is how a model keeps track of what "it" refers to three sentences back.
From text predictor to assistant
A model trained only to continue text is not yet an assistant: asked a question, it might continue with more questions. Assistants are made in further training stages:
- Instruction tuning, a form of fine-tuning: training on many examples of requests and good answers, so the model learns to respond rather than continue.
- Learning from preferences: people (and increasingly other models) compare pairs of answers, and the model is trained towards the preferred ones. The best-known method is reinforcement learning from human feedback (RLHF).
These stages shape tone, format and what the model declines to do. They add relatively little knowledge; that comes from the first stage.
The context window
Everything a model takes into account while answering has to fit in its context window: the instructions, the conversation so far, any documents you include, and the answer it is writing, all counted in tokens. Context windows have grown a great deal, but they are still finite, and models tend to use information in a very long context less reliably than in a short one. Putting the right few passages in front of the model usually beats putting everything.
What a language model is not
- It is not a database. It does not look facts up; it produces likely text. When the likely text is wrong, it states it just as fluently as a correct answer. This is usually called hallucination, and it is the main reason not to trust an answer that cannot be checked.
- It does not know what happened after its training. Its knowledge stops at a cut-off date unless current information is put in the context.
- It does not learn from your conversation. Within a chat it can use what you said earlier because that text is in its context window. Its weights do not change, and once the conversation is gone, so is what it "learned".
The usual fix for the first two is to give the model the facts at answer time, from your own documents or a search: the approach called RAG.
Building with one
When we put a language model into a product, a few questions decide most of the design:
- Which size? Larger models are generally better at reasoning and following complex instructions; smaller ones are faster and cheaper, and can run on your own hardware or even on a device (we wrote about running models at the edge).
- How will you know it works? Collect real examples of the inputs your users will send, write down what a good answer is, and measure every candidate model and prompt against them. Impressions from a few tries are misleading.
- What happens when it is wrong? Wherever an error is costly, show sources, keep a person in the loop, or let the model answer only from material you supply.
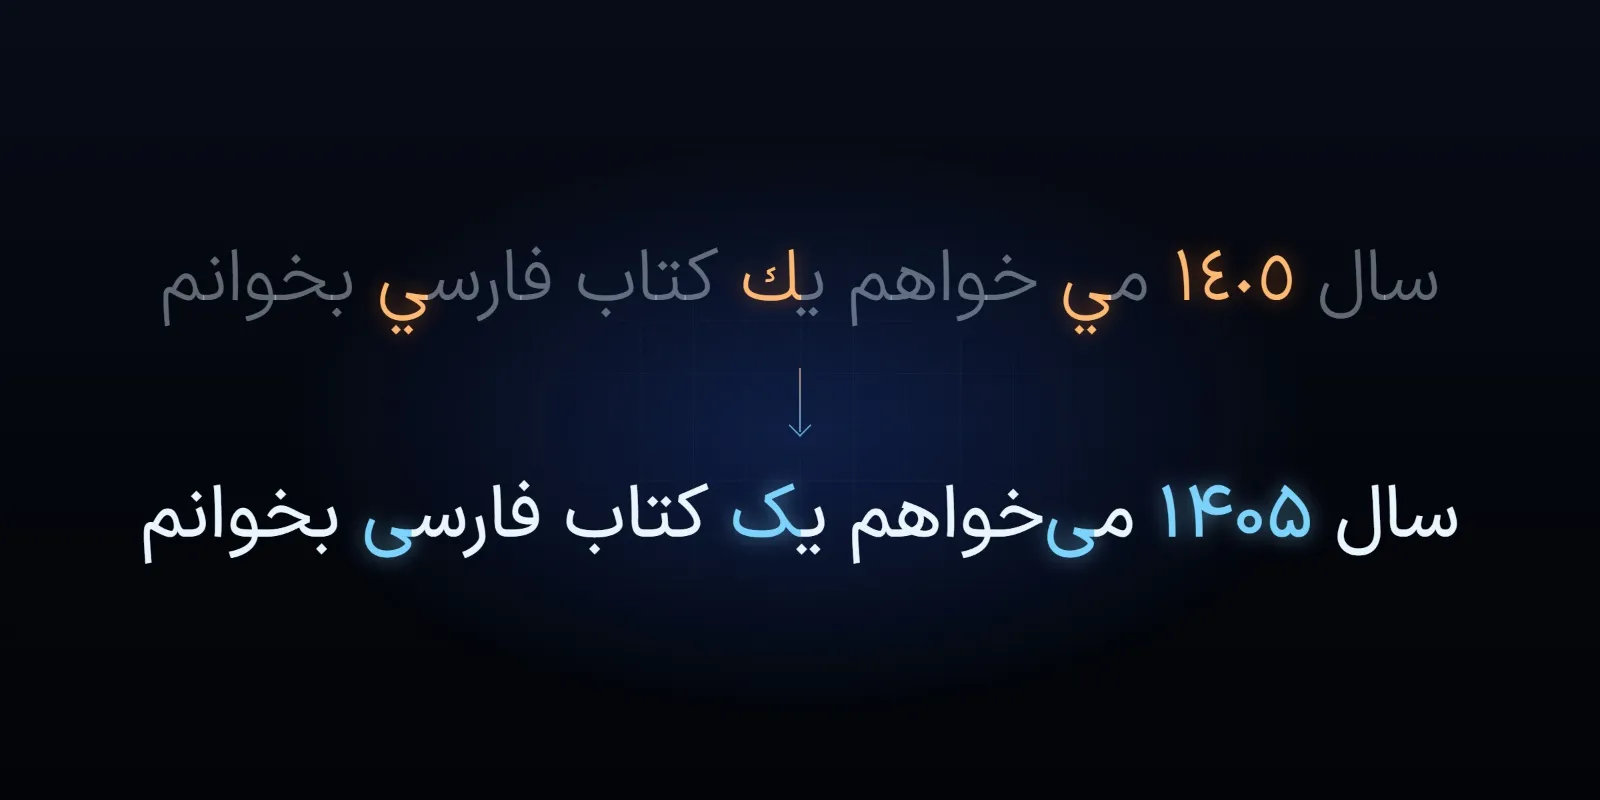
- Which language? If your users write in Persian, test in Persian. Quality, speed and token cost can all differ from English, and only your own tests will tell you by how much. The text itself needs work first, which we cover in processing Persian text with AI.