5 min read
Fine-tuning or RAG? Bringing organisational knowledge into language-model applications
The uses and limitations of retrieval and fine-tuning, and when combining them can be useful.
A general-purpose language model has read a large part of the public internet. It can explain a tax rule or write a polite email in three languages. What it has never seen is your price list, your contracts, your product catalogue or the way your support team answers a refund request. Ask it about those and it will either say it doesn't know or, worse, make something up that sounds right.
There are two main ways to close that gap: retrieval-augmented generation (RAG), where the model looks your knowledge up at the moment it answers, and fine-tuning, where you train the model further on examples from your own work. They solve different problems, and choosing the wrong one is one of the most common reasons an AI project stalls.
RAG: look it up at answer time
In a RAG system the model itself is not changed. Instead, your documents are prepared once:
- They are split into passages (often called chunks), a few paragraphs each.
- Each passage is turned into an embedding: a list of numbers that captures what it is about, so that passages with similar meaning end up close together.
- The embeddings go into an index built for fast similarity search (a vector database, or a search engine that supports vectors).
When someone asks a question, the question is embedded the same way, the closest passages are retrieved, and they are placed in the prompt together with the question. The model then answers from the text in front of it.
What RAG is good at:
- Knowledge that changes. Update a document and the next answer uses it. Nothing needs retraining.
- Showing sources. Because you know which passages were retrieved, the answer can link to them, and a person can check it.
- Access control. You can retrieve only from documents the current user is allowed to see.
- Any model. The same index works with a hosted model today and a self-hosted one tomorrow.
Where it struggles:
- Retrieval is the ceiling. If the right passage is not retrieved, the model cannot use it. Most RAG failures are search failures, not model failures.
- Bad chunking. Splitting documents every fixed number of characters cuts tables in half and separates a heading from its paragraph. Splitting along the document's own structure (sections, rows, articles of a contract) usually works much better.
- Context limits and latency. Retrieved text takes up room in the prompt and adds a search step to every answer.
- It does not change behaviour. RAG gives the model facts. It does not teach it your format, your tone or which questions it should refuse.
Fine-tuning: adapt the model to the task
Fine-tuning continues a model's training on examples of the task: an input and the output you want for it, hundreds or thousands of times. The model's weights change, so the behaviour sticks without being explained in every prompt.
What fine-tuning is good at:
- Consistent format and tone. Always answering in your template, always in Persian, always citing the clause number.
- Domain language. Jargon, abbreviations and the way people in your field actually write.
- Shorter prompts. Instructions that used to take a page of prompt are learned once.
- Small, fast models for narrow tasks. A small model fine-tuned on one job (classifying support tickets, extracting fields from invoices) can match a much larger general model on that job, at a fraction of the cost and latency.
Where it struggles:
- It needs good data. The model learns what the examples show, mistakes included. Collecting and cleaning examples is usually most of the work.
- Facts go stale. Whatever was true when you trained is what the model remembers. Updating it means training again.
- No sources. A fine-tuned model cannot tell you where a fact came from.
- Narrowing. Train too hard on one task and a model can get worse at others.
Full fine-tuning updates every weight and needs serious hardware. Parameter-efficient methods such as LoRA train small adapter matrices next to the frozen original weights instead, which cuts the memory and cost dramatically and lets you keep several adapters for different tasks on one base model.
A quick way to decide
| Question | Lean towards |
|---|---|
| Do the facts change every week? | RAG |
| Must every answer show its source? | RAG |
| Should different users see different documents? | RAG |
| Is the problem the format, tone or behaviour? | Fine-tuning |
| Do you need a small, fast model for one narrow task? | Fine-tuning |
| Does the model need to speak your field's language fluently? | Fine-tuning |
Why most products use both
In practice the two are not rivals. A common pattern is to fine-tune for behaviour and retrieve for knowledge: the fine-tuned model knows how to answer (your format, your language, when to say "I don't know"), and retrieval tells it what is true today. Each covers the other's weakness.
Measure before you choose
The most useful thing you can do before writing any code is to build a test set: fifty to a few hundred real questions, each with an answer an expert agrees is right. Then measure two things separately:
- Retrieval: for each question, did the right passage come back in the top few results?
- Answers: given the right passage, was the answer correct, complete and in the right form?
If retrieval is poor, no amount of fine-tuning will help, and you should work on chunking, search and metadata first. If retrieval is good but responses are inconsistent, that is where fine-tuning earns its cost.
A note for Persian
Two practical points if your documents are in Persian:
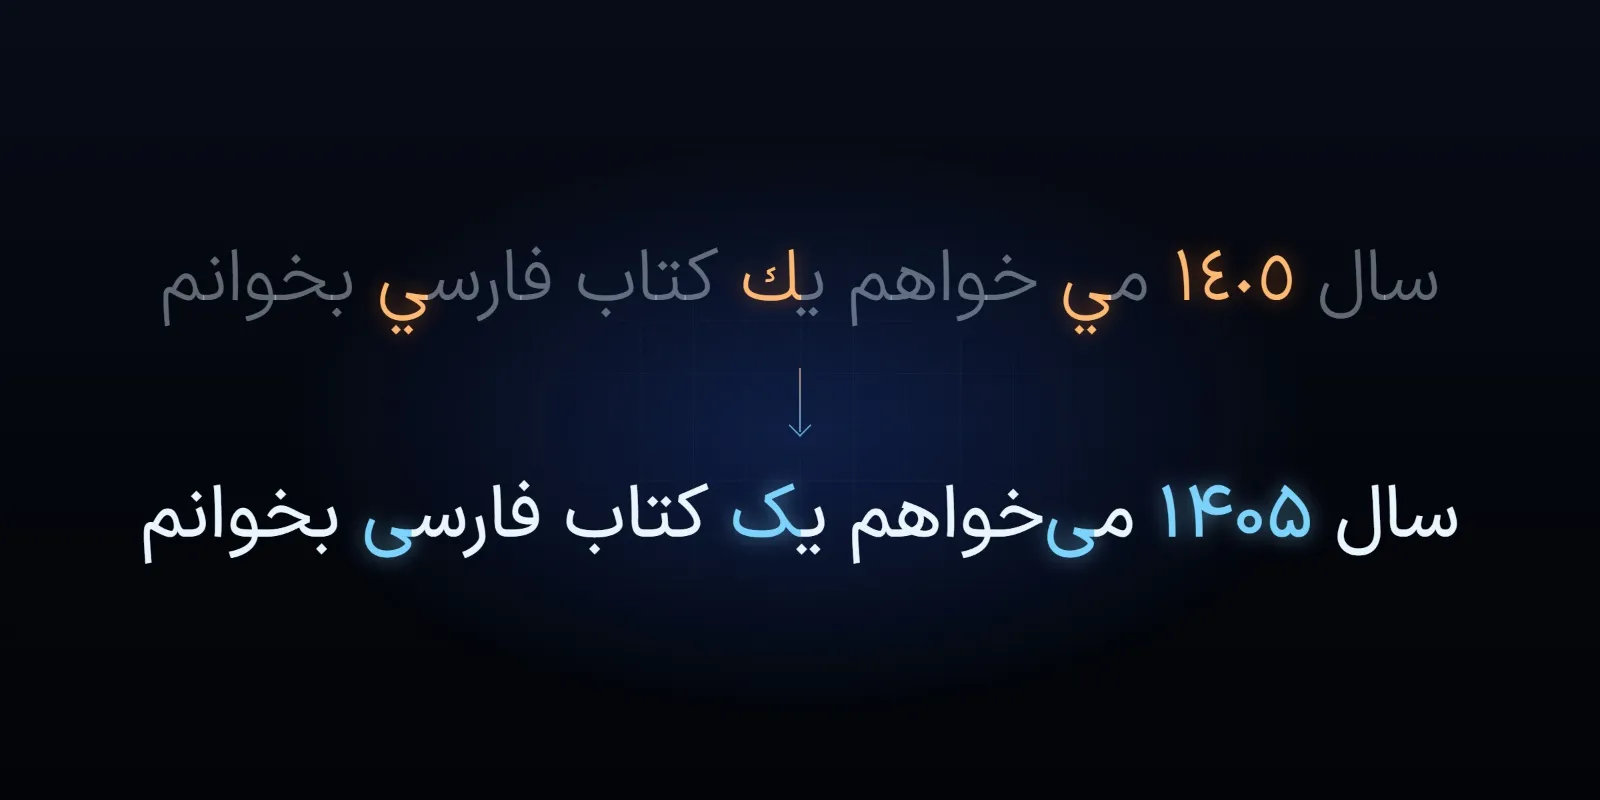
- Normalise the text before indexing. Persian text often mixes the Arabic forms of some letters (ي and ك) with the Persian ones (ی and ک), and uses the zero-width non-joiner (نیمفاصله) inconsistently. To a search index these are different characters, so the same word written two ways will not match unless you normalise both your documents and the questions.
- Expect more tokens. Many models' tokenizers split Persian into more tokens than English for the same meaning, which means higher cost and less room in the context window. It is worth measuring with your actual model before estimating costs.
Contact us to discuss how to incorporate organisational knowledge into an AI product.